How to Tell AI Slop From Human Writing: Ten Structural Features From 13,500 Blog Posts
AI-generated blog posts read familiar for a reason: they share a shape. A 13,500-post study separates the two by structure alone with a detection score of 98.0 out of 100, and rewording does not move it. The ten features behind it, and what human writing does differently.
Most AI-generated blog posts do not read badly. They read familiar. The title promises a result, the first paragraph lists what is coming, every section announces itself, and the last paragraph says it all again. You notice before you can say why.
That feeling has a shape, and the shape can be measured. At Sitefire we took 13,500 blog posts, set aside everything about their wording, and kept only how each post was built: what it promises, where it makes its point, how it moves from section to section, how it ends. 2,250 of the posts were written by people at 268 companies before ChatGPT existed. The other 11,250 were written from the same briefs by five AI models: GPT-5.4, Claude Sonnet 4.6, Gemini 3 Flash, DeepSeek V3.2, and Kimi K2.5.
From the shape alone, a classifier told the AI-generated posts from the human ones with a detection score of 98.0 out of 100, on companies it had never seen. The score works like accuracy with one correction: it weighs the human posts and the AI posts equally, so a detector cannot look good by calling everything AI. That shortcut scores 45.5. Perfect is 100. (The technical name is macro-F1.) When we then had each AI model reword its own posts, the score did not move. A rewrite changes the sentences and leaves the shape untouched, and the shape is what gives the post away.
That matters if you publish. Google's policy on scaled content abuse already judges mass-produced pages by outcome rather than method, and YouTube already reads structural signals such as upload pacing. Whether a search engine reads these ten features today is untested. But your readers already do.
Can you tell AI writing from human writing without reading the words?
Yes. Structure alone separates AI-generated blog posts from human ones with a detection score of 98.0 out of 100. Word count alone scores 45.5, the same score a detector gets by labeling every post AI without reading it.
Word-level detectors have two limits. The best of them score a perfect 100.0 on the same detection scale, as long as nobody edits the posts, and fall under rewording, as Krishna et al. (2023), Sadasivan et al. (2023), and Weber-Wulff et al. (2023) measured. The other is that a word-level score, even when right, says nothing about the post: not what it does, not which AI model wrote it.
Structure sits one level deeper, and it answers both limits. We scored each post on 214 questions about how it is built and how it is worded. A classifier reading only the 187 questions about structure, with every question about wording removed, reaches 98.0 out of 100. The 27 questions about wording alone reach 88.1, and word count alone cannot tell the two apart.
| What the classifier reads | Detection score (0 to 100) |
|---|---|
| Structure only (187 features) | 98.0 |
| Style features only (27 features) | 88.1 |
| Word count only | 45.5 |
| Best word-level detector, unedited text | 100.0 |
Detection score on posts from companies the classifier never saw in training. Labeling every post AI scores 45.5. Perfect is 100.
The classifier was tested on companies it never saw in training, which is the strict test, because company websites resemble themselves. A classifier that scores that high on structure alone is reading something specific.
What gives an AI-generated post away?
Ten core structural features give an AI-generated post away, each a choice about how the post is built rather than which words it uses. The four with the largest human-AI gap: a payoff promised in the title, a summary or synthesis stage, a restated thesis at the close, and no participation pathway for the reader.
A core feature is one that AI posts and human posts answer differently, by a wide margin, and consistently across all five AI models. The ten are below in the order a reader meets them, as a chart and again as a table you can copy into a checklist.
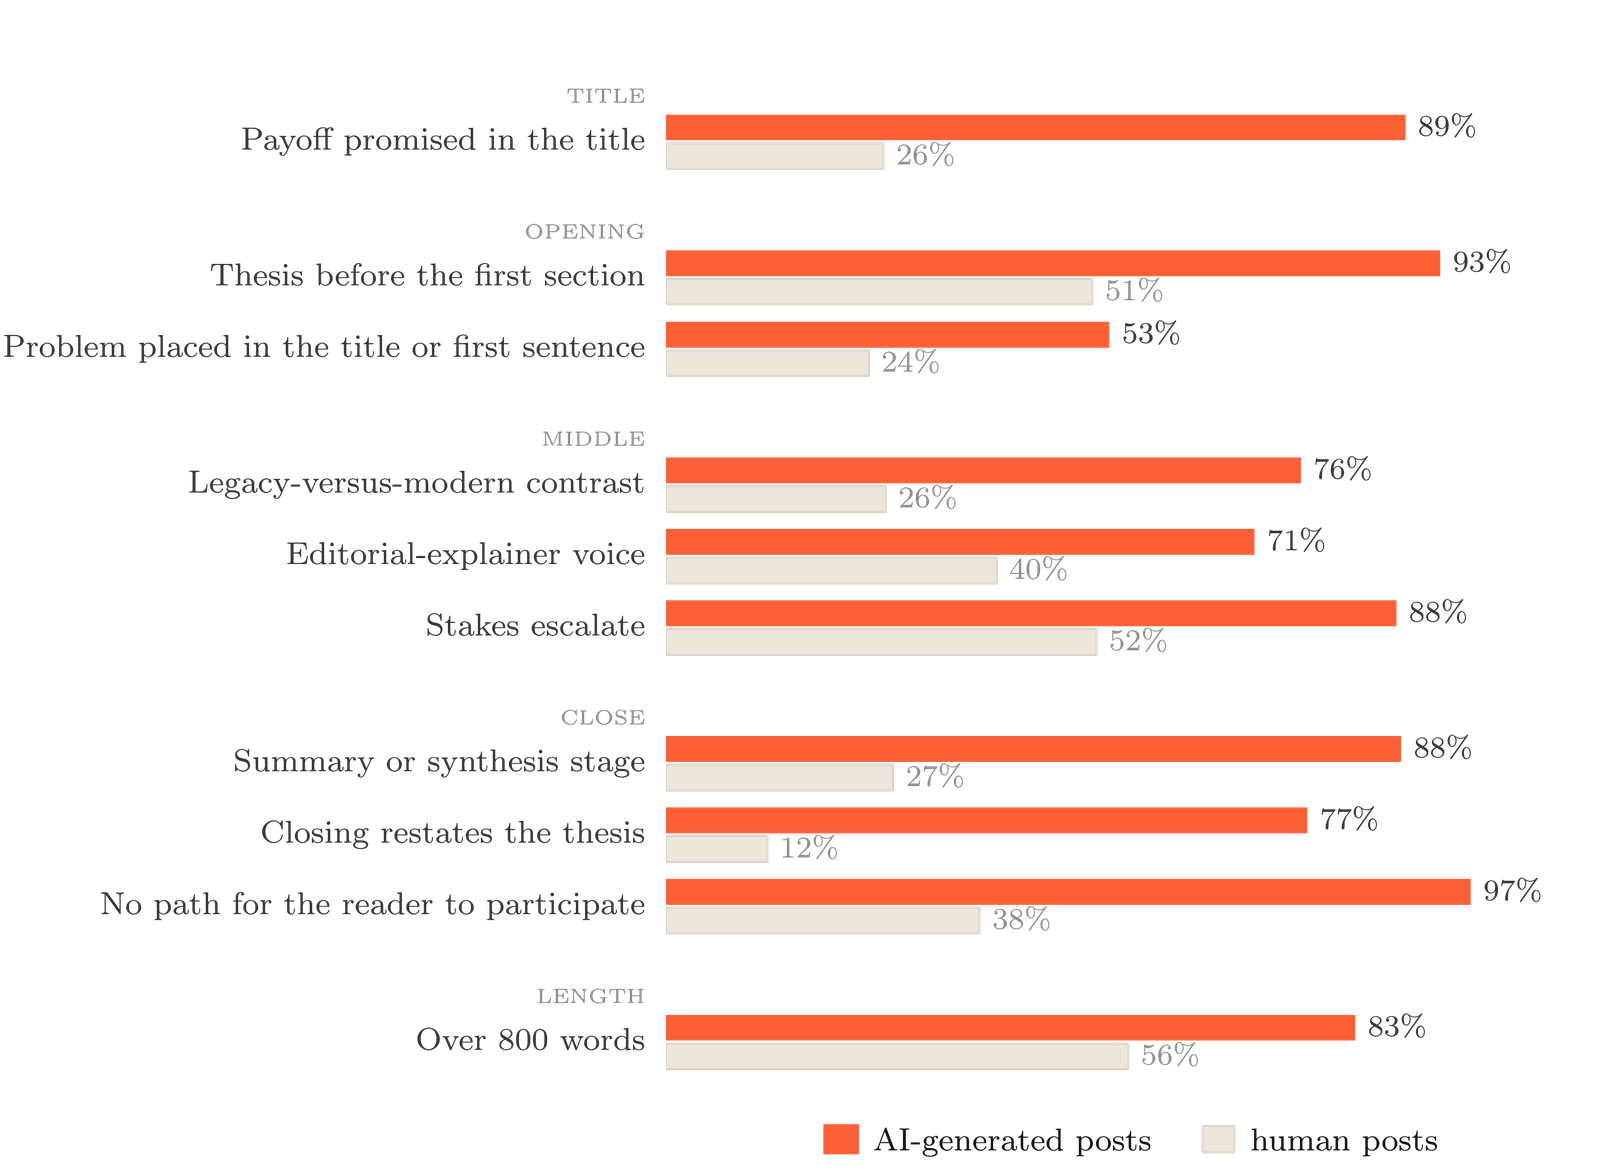 Share of AI-generated posts and human posts showing the AI-leaning value of each core feature, in the order a reader meets them. 11,250 AI-generated posts, 2,250 human posts. Problem placement counts a post when the problem appears in the title or the first sentence.
| Where in the post | Core feature | AI posts | Human posts |
|---|---|---|---|
| Title | The payoff is promised in the title | 89% | 26% |
| Opening | The thesis comes before the first section | 93% | 51% |
| Opening | The problem is placed in the title or first sentence | 53% | 24% |
| Middle | A legacy-versus-modern contrast frames the argument | 76% | 26% |
| Middle | The voice is an editorial explainer, not a person | 71% | 40% |
| Middle | The stakes escalate as the post goes on | 88% | 52% |
| Close | A summary or synthesis stage | 88% | 27% |
| Close | The close restates the thesis | 77% | 12% |
| Close | No participation pathway for the reader | 97% | 38% |
| Length | Over 800 words | 83% | 56% |
Put the AI-leaning values together and you get the tidy, self-announcing blog post, written in an editorial-explainer voice, with no participation pathway: no place for the reader to reply, join, apply, or try. The AI post is written at you.
You have read this post before. The title promises the payoff: "How to Cut Onboarding Time in Half." The opening states the thesis and announces the flow: "In this post, we'll cover why onboarding stalls, three fixes that work, and how to measure the difference." The close restates the thesis: "In short, structured onboarding saves time."
Length is one of the two weakest of the ten core features, and it is not doing the work. Four of the five AI models run longer, GPT-5.4 averaging 1,541 words against a human average of 1,186, so the study reran the test on a subsample in which human and AI posts were matched on length. The detection score came out at 98.1, against 98.0 without matching.
The obvious objection is that all of this is fixable in an afternoon: run the draft back through the AI model and tell it to vary the sentences and lose the stock phrases. If the signature lives in the words, that pass should remove it too. We tested it.
Does rewording remove the structural signature?
No. Reworded by the same AI model that wrote it, all but 5 of the 1,450 AI-generated posts in the test split still read as AI-generated. The structural detection score moves from 98.0 to 98.1 out of 100.
We had each of the five AI models reword its own posts, passage by passage, using the seven kinds of AI-writing tics that professional editors catalogued in earlier work, and told it to keep every claim and link. The rewrite was not light: on average, 73% of a post's 13-word runs were gone afterward, and Gemini 3 Flash kept almost none of them.
Style features felt it, dropping from 88.1 to 87.1, as a wording attack should. Structure held. Some feature answers did change, 15.6% in a spot check of 20 posts, against about 10.7% when the same text is simply scored twice, but the changes were scattered across posts and features rather than pointed toward the shape of a human post. The reworded post still promised the payoff in its title and still closed on a restatement, because none of that lives in the words.
| What the classifier reads | Before rewording | After rewording |
|---|---|---|
| Structure only (187 features) | 98.0 | 98.1 |
| Style features only (27 features) | 88.1 | 87.1 |
Detection score, 0 to 100, on the same 1,740 test posts before and after every AI post was reworded by its own model.
How much was rewritten made no difference. Gemini 3 Flash replaced almost every 13-word run and was caught at the same rate as Claude Sonnet 4.6, which replaced under half.
| AI model | Share of 13-word runs replaced | Detection score after rewording (0 to 100) |
|---|---|---|
| Gemini 3 Flash | 99.7% | 98.1 |
| Kimi K2.5 | 85.9% | 97.6 |
| GPT-5.4 | 82.5% | 98.1 |
| DeepSeek V3.2 | 51.1% | 98.1 |
| Claude Sonnet 4.6 | 46.5% | 98.1 |
How much of each model's text the rewrite replaced, and how well structure alone still identified the reworded posts. 1,450 reworded posts.
We had expected the opposite. Commercial writing is persuasion in a brand voice, so before we ran the study we predicted that wording would carry more of the signal than structure. It carried 9.9 points less on the detection score: 88.1 for wording against 98.0 for structure.
The two readings also miss different posts. Of 1,740 test posts, the structure reading gets 19 wrong and the wording reading 101, and only 4 posts fool both. If structure were wording under another name, they would miss the same posts. They do not, and only one of the two survives a rewrite.
The test covers rewording by the same AI model that wrote the post. Dedicated humanizer tools, which can restructure as well as reword, were not part of our study. To know whether a post reads as AI-written, look at what it does, not which words it uses.
Nor is the shape the habit of one model. All five share it, and each adds a few features of its own: Claude Sonnet 4.6 reaches for numbered procedures, GPT-5.4 for numbers and caveats, Gemini 3 Flash for self-reference, DeepSeek V3.2 for operational thresholds, and Kimi K2.5 for authority claims and commercial calls to action. Those additions are enough for the classifier to name the right one of six sources 79.3% of the time, where a blind guess is right one time in six, 16.7%, and when it errs it almost always mistakes one AI model for another, not a human for a model. That leaves one thing to explain: what the human posts were doing instead.
What does human writing do differently?
Human blog posts occupy the rare regions of structural space, and they get there by leaving the signposts out.
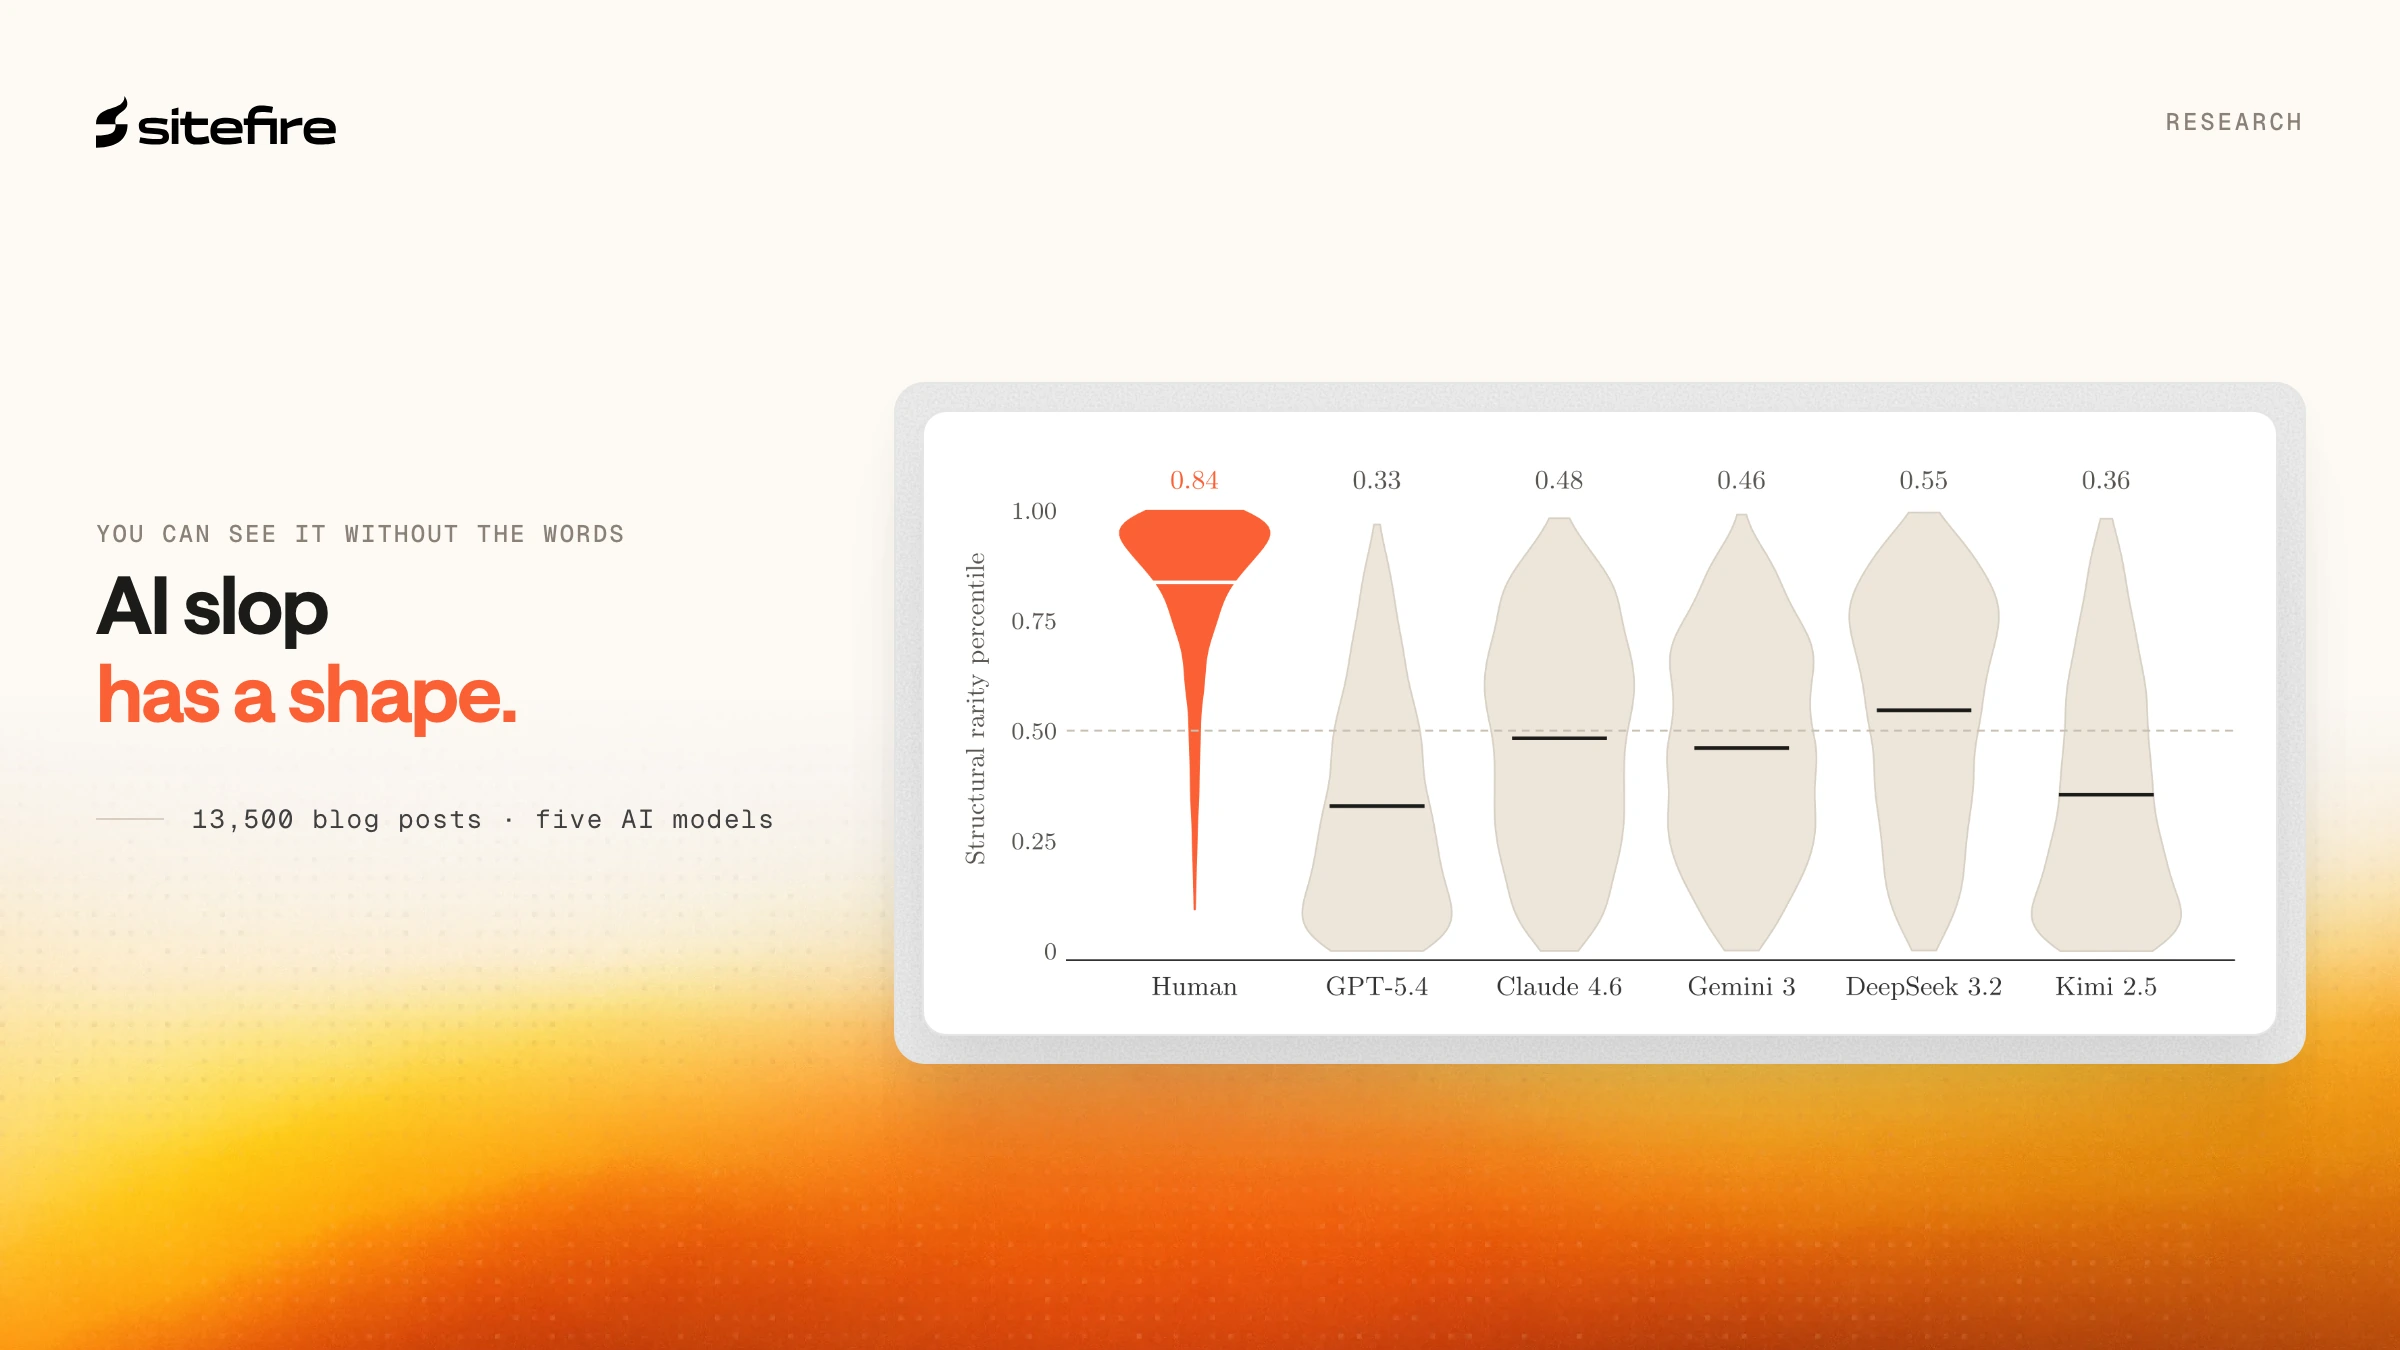
We gave every post a rarity score from 0 to 1: how unlike its structure is from the 25 posts built most like it. A post built the way many others are built scores near 0. A post few others resemble scores near 1. Human posts average 0.84, a structure rarer than 84% of the posts it is ranked against. AI-generated posts average 0.44, and every one of the five AI models sits below the human mean, from DeepSeek V3.2 at 0.55 down to GPT-5.4 at 0.33.
Place the posts by their structure alone and two regions appear. The 11,250 posts from five different AI models pile into one, the 2,250 human posts sit in the other, with open space between them. The human region is also wider: a human post sits 1.43 times farther from its ten nearest structural neighbors than an AI post does.
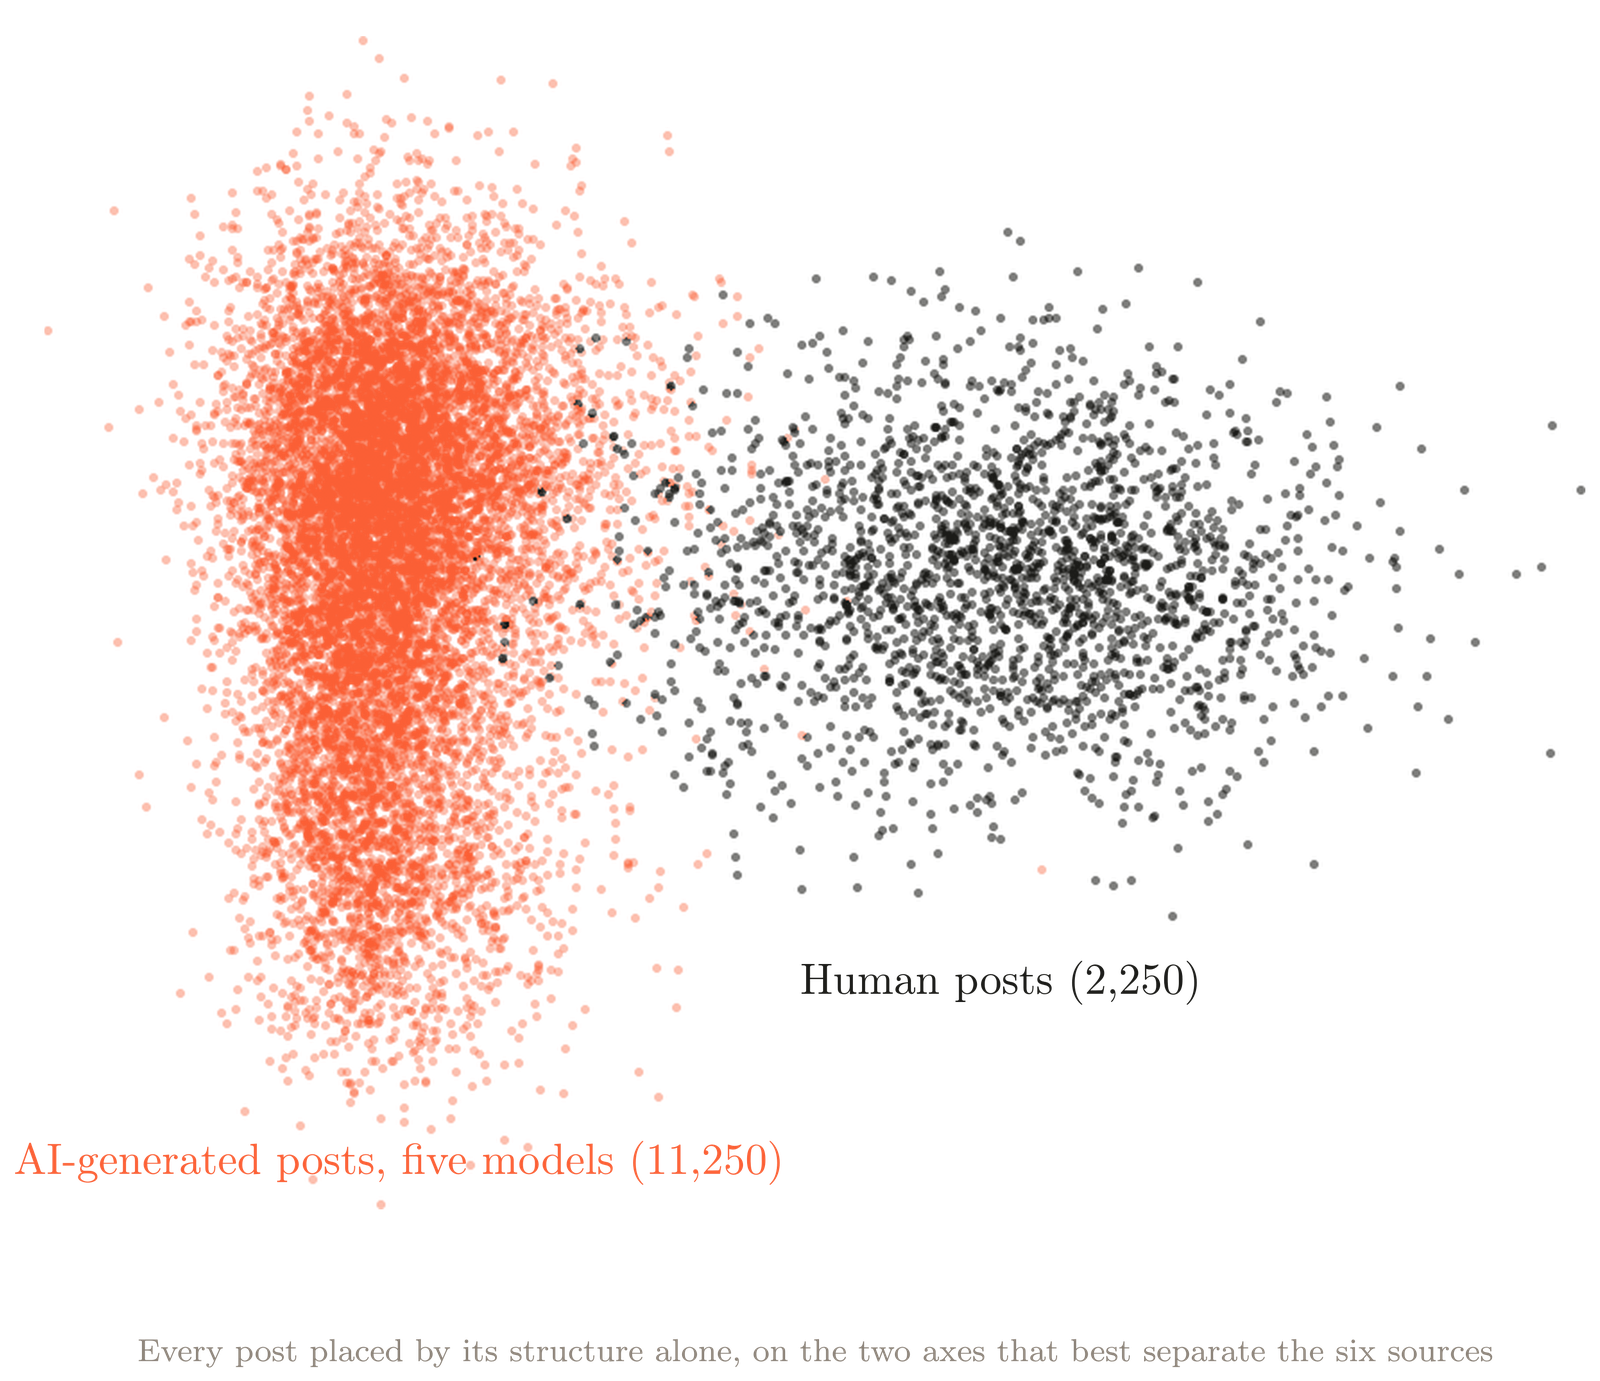 Every post placed by its structure alone, on the two axes that best separate the six sources. AI-generated posts in Amber, human posts in ink. The five AI models overlap each other and sit apart from the human posts.
The gap is sharpest at the top: of the rarest 1% of all posts, 149 are human and 4 are AI, and 47.7% of human posts sit in the rarest tenth against 2.8% of AI posts. Researchers use rarity as a stand-in for originality. Measured as an effect size, the gap between the human and AI averages is 1.83, more than twice the 0.83 StoryScope found in fiction. On that scale 0 means no gap, and anything above 0.8 already counts as large.
The human-leaning feature values read as absences: no thesis announced before the first section, no restated thesis at the close, no legacy-versus-modern contrast. Stakes stay put, posts run shorter, and the problem arrives when the writer gets there, not in the title. The human post is the one that does not tell you it is about to make a point, does not sum itself up at the end, and leaves you somewhere to go next.
Human posts are not better written by this measure. They are less alike. That means the instrument reads both ways: the features that flag the common configurations of AI posts also locate the rare configurations of human writing. Originality here is structural, and it can be measured.
What do you change on Monday?
Check your last five posts against the ten core features, then restructure rather than reword.
1. Check the ten core features. Count the AI-leaning values each post shows. A classifier reading only these ten still scores 93.5 out of 100, against 98.0 with all 187 structural features. Add up the rates in the table and the average AI-generated post shows about eight of the ten; the average human post, three or four. The study did not test a cutoff, so treat the count as a reading, not a verdict: the closer to eight, the more the shape is the problem rather than the words.
2. Restructure, do not reword. Rewording moved structural detection by a tenth of a point. Drop the paragraph that announces what is coming, end on the reader's next step instead of a restatement, and give the reader a way to reply, join, apply, or try. Those are the core features with the largest human-AI gaps, and the last one is the cheapest to add.
3. Test yourself. Spot the Slop, Sitefire's five-round game, puts two posts side by side, one by a person and one by an AI model, and the reveal shows the structural feature that gave it away.
The Bottom Line
AI-generated blog posts have a shape, and it sits one level below the words. Structure alone identifies them with a detection score of 98.0 out of 100, the score does not move when the same AI model rewords its own post, the shape is shared across five AI models, and a reader can check it in the time it takes to skim: payoff in the title, thesis before the first section, a summary or synthesis stage at the close, no participation pathway. Text restructured on purpose or edited by a person is untested, and that is the boundary.
Human writing sits in the regions the AI models rarely reach, and it gets there by leaving things out. Run this post against the table and it shows eight of the ten, including the summary and the restated thesis you are reading now. We counted. The two it does not show: the voice is a person who ran the study, and it leaves you somewhere to go next. The signature fits in one sentence: AI writes the tidy, self-announcing post; humans just write the thing.
Frequently Asked Questions
Does this apply to my industry, or only to B2B blogs?
The 2,250 human posts are B2B blog posts from 268 company websites, mostly US, across software, e-commerce, services, fintech, developer tools, and health. The detection score stayed between 96.5 and 100 out of 100 in every vertical large enough to measure, and StoryScope found the same effect in fiction, a genre with none of these features. B2C content was not in the corpus, and our claim covers the five AI models we tested.
Do Google and AI search engines use signals like this?
Not that we can show. Google's policy on scaled content abuse sanctions mass-produced pages by outcome rather than method, and YouTube reads structural signals against mass-produced video, so structural features are a candidate signal of a kind platforms already act on. Whether any AI search engine reads these ten core features today is untested.
Can I make an AI-generated post pass by restructuring it?
Restructuring changes the shape the classifier reads, so a post rebuilt without the thesis announced before the first section and the restated thesis at the close, and with a participation pathway for the reader, would look more human on these ten core features. Our study did not test that attack. The useful reading runs the other way: restructuring is what makes a post read as written by a person.
How was the study validated?
Because an AI model scored every post against every feature, we checked the scorer against people. Two annotators, both Sitefire-affiliated, independently scored a sample of posts. Agreement is measured as kappa, which strips out the agreement two graders would reach by luck: 0 is luck, 1 is perfect, and 0.60 is the usual bar for a reliable instrument. That bar was fixed before annotation began. The annotators reached 0.928 with each other and 0.946 with the AI scorer, above StoryScope's 0.739 and 0.839.
Methodology note
Our study is "SlopShape: Identifying AI-Generated Commercial Web Content" (Madler, 2026, arXiv:2609.15369), Sitefire's domain-transfer replication of StoryScope on commercial posts. Human posts: 2,250 blog posts from 268 company websites, archived 2008 to 2022. AI-generated posts: a content brief inferred from each human post, naming the publishing company as the one commissioning the post, given to GPT-5.4, Claude Sonnet 4.6, Gemini 3 Flash, DeepSeek V3.2, and Kimi K2.5, yielding 11,250 AI-generated mirror posts. Features: 214, 187 structural and 27 style, scored by an AI model and validated in a human gold-annotation session (kappa 0.928 between the two human annotators and 0.946 between the humans and the AI scorer, where 1 is perfect agreement and 0.60 was the bar set in advance). The ten structural features in this post are the study's ten core features, and the rates in the table are the share of posts showing each feature's AI-leaning value, from the study's released per-feature answer distributions; problem placement counts a post when the problem appears in the title or opening sentence. Classifier: gradient-boosted trees, tested on held-out companies. The headline detection score of 98.0 carries a 95% confidence interval of 96.7 to 99.2: rerun the test on a different draw of companies and the score lands in that range 19 times out of 20. The rarity scores, the rarest-1% counts and the two-regions figure use the 12,900 posts that entered classification; the 600 posts used to discover the features are excluded. Some human posts are interviews, transcripts, or roundups, formats the AI mirrors rarely produce; on the 86.5% of human posts that are regular self-contained articles, structure alone still scores 97.5 out of 100. Every effect StoryScope reported replicates, in the same direction and at larger magnitude, without any claim that commercial writing is easier to separate than fiction.
Two limits are inherited from StoryScope: the AI models wrote from a brief while the human authors wrote from full business context, and the human posts predate ChatGPT while the AI posts were generated in August 2026, although structure does not predict when a human post was written. The corpus is less than a quarter the size of StoryScope's (2,250 human posts against 10,272), so the per-model attribution scores and the rarest-1% counts are the least precise numbers in this post. Not tested: dedicated humanizer tools, edited or human-AI collaborative text, and AI models other than the five studied.
Part of Sitefire's product writes blog posts for customers with AI models, and both human annotators are Sitefire-affiliated. The study's methods, code, prompts, and aggregate results are public in the verification repository. Per-post data is available to researchers on request.
Sources
- Madler, J. (2026). SlopShape: Identifying AI-Generated Commercial Web Content. arXiv:2609.15369. https://arxiv.org/abs/2609.15369. Verification package: https://github.com/pulse-energy-eu/slopshape
- Russell, J., Rajendhran, P., Pham, C., Iyyer, M., and Wieting, J. (2026). StoryScope: Investigating idiosyncrasies in AI fiction. arXiv:2604.03136. https://arxiv.org/abs/2604.03136
- Krishna, K., Song, Y., Karpinska, M., Wieting, J., and Iyyer, M. (2023). Paraphrasing evades detectors of AI-generated text, but retrieval is an effective defense. NeurIPS 2023. https://arxiv.org/abs/2303.13408
- Sadasivan, V. S., Kumar, A., Balasubramanian, S., Wang, W., and Feizi, S. (2023). Can AI-Generated Text be Reliably Detected? https://arxiv.org/abs/2303.11156
- Weber-Wulff, D., et al. (2023). Testing of detection tools for AI-generated text. International Journal for Educational Integrity, 19(26). https://doi.org/10.1007/s40979-023-00146-z
- Chakrabarty, T., Laban, P., and Wu, C.-S. (2025). Can AI writing be salvaged? Mitigating Idiosyncrasies and Improving Human-AI Alignment in the Writing Process through Edits. Proceedings of CHI 2025. arXiv:2409.14509. https://arxiv.org/abs/2409.14509
- Google (2024). Spam policies for Google web search: scaled content abuse. https://developers.google.com/search/docs/essentials/spam-policies
- Mathur, A., et al. (2026). Scalable Detection of Adversarial Synthetic Slop and Coordinated Media Abuse: A LoRA-Enabled Multimodal Defense System. Google Research. https://storage.googleapis.com/gweb-research2023-media/pubtools/1039291.pdf